Robust AI Models by Learning from the Hard-to-Learn
Problem
AI models learn whatever patterns help them score well on their training data, including patterns that are only coincidences. Researchers call these spurious correlations. A language model might learn that a certain word usually signals a certain answer, and then rely on that shortcut instead of actually understanding the text.
Shortcuts work well on data that looks like the training set, which is why they are easy to miss in testing. They fail when the model meets real-world inputs that break the pattern: a new customer phrasing, a different product category, a change in how people write. For a business, that shows up as a model that looked accurate before launch and then makes confident mistakes in production, often on exactly the unusual cases that matter most.
The paper notes that minority examples, the data points that contradict the common shortcut, are known to help models generalise better. The difficulty is finding them: usually nobody knows in advance which shortcuts are hiding in a dataset.
Also applicable to
- Customer service and support: chatbots and ticket routing that hold up when customers phrase things in new ways.
- Finance and banking: text models for documents, complaints and risk signals that do not lean on surface cues.
- Healthcare: clinical text models that generalise beyond the patterns of one hospital's notes.
- Retail and e-commerce: product classification and search that stay accurate as catalogues change.
- Search and question answering: answer systems that respond to the evidence, not to a familiar phrasing.
Solution / Approach
The Elementera team's research on robustness is captured in Increasing Robustness to Spurious Correlations using Forgettable Examples, a paper co-authored by Elementera co-founder Soroush Mehri with Yadollah Yaghoobzadeh, Remi Tachet, T. J. Hazen and Alessandro Sordoni, and published at EACL 2021.
The approach has two steps.
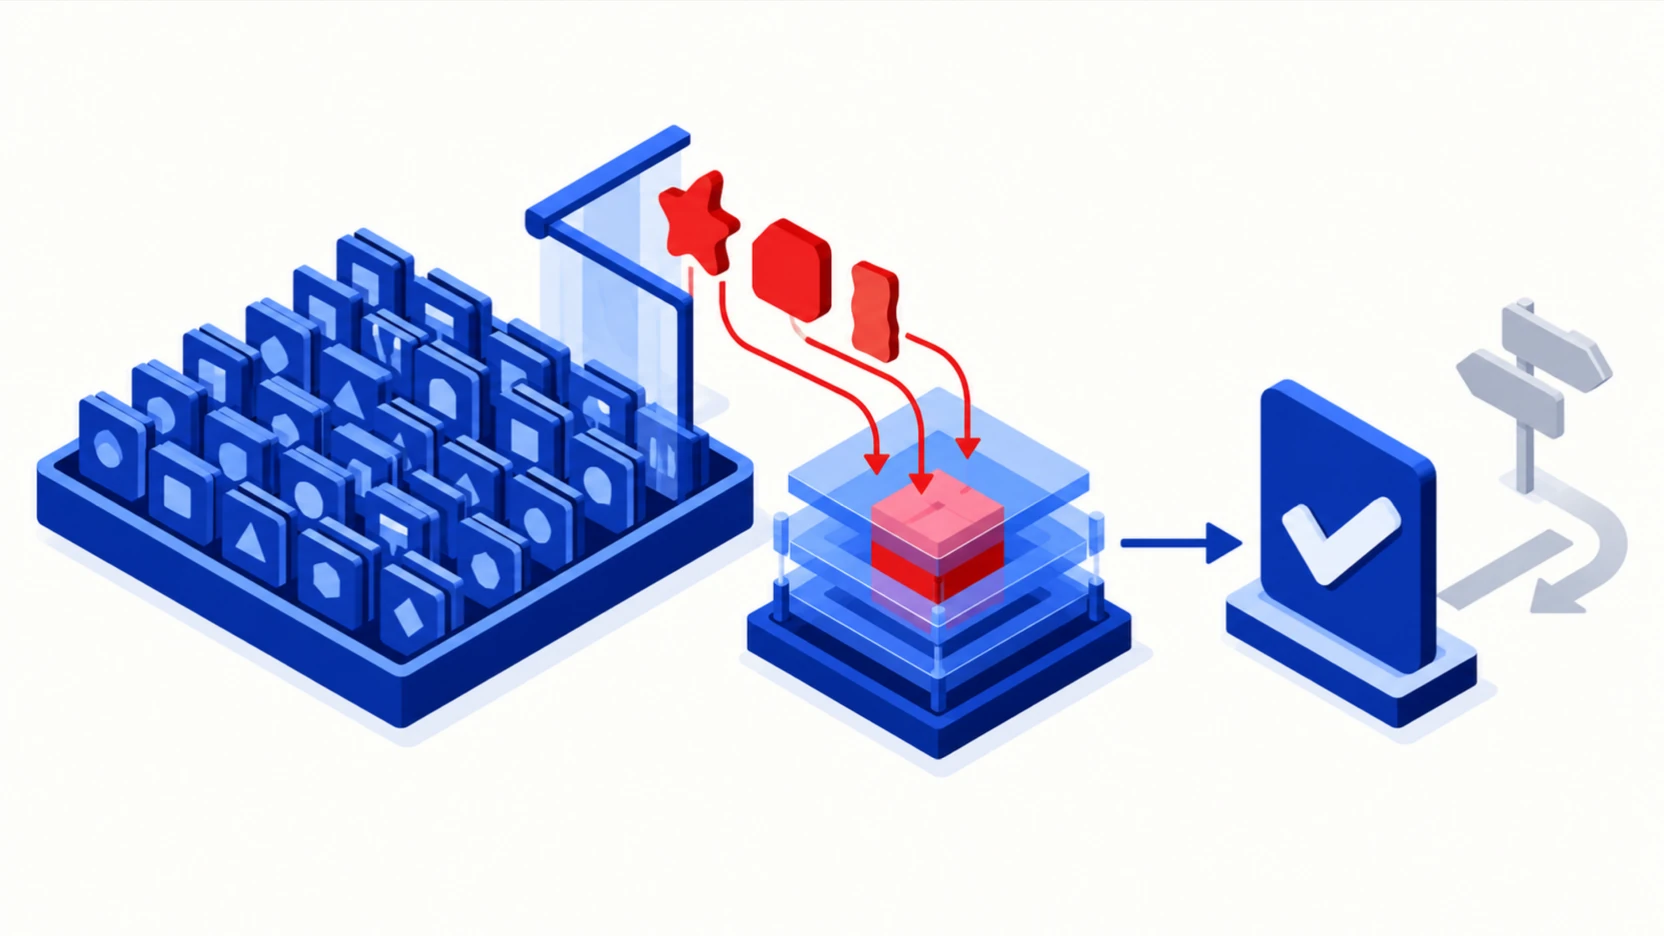
- Find the hard-to-learn examples automatically. The paper proposes using example forgetting to find minority examples without any prior knowledge of which spurious correlations exist. Forgettable examples are training examples the model either learned and then forgot during training, or never learned at all. The authors show empirically that these examples are related to the minorities in the training sets.
- Fine-tune twice. The model is first fine-tuned on the full training data, then fine-tuned a second time on the minority examples only. This second pass pushes the model toward the cases its shortcuts cannot explain.
The appeal is practical: the method uses the model's own training behaviour to point at the data that matters, instead of asking people to guess and label every possible shortcut in advance.
Why this matters for a company using AI: robustness is what separates a model that demos well from one you can rely on. A method that surfaces the cases a model struggles with, and then trains on them, directly targets the failures that cost money and trust after deployment.
Impact
According to the paper, the approach delivered substantial improvements in out-of-distribution generalisation on three well-known language datasets: MNLI (natural language inference), QQP (duplicate question detection) and FEVER (fact verification).
For businesses, this research means:
- More reliable models in production: less dependence on shortcuts that break on new data.
- No need to know the shortcut in advance: forgettable examples are found from training dynamics alone.
- A simple training recipe: a second round of fine-tuning on a targeted subset fits into existing pipelines.
- Insight into AI failure modes: the same understanding helps explain why AI systems sometimes answer from a learned shortcut instead of from the evidence in front of them, which is central to how Elementera studies AI answers today.
Technologies
- Pre-trained language models: fine-tuned for natural language understanding tasks.
- Example forgetting: tracking which training examples a model learns, forgets or never learns.
- Targeted fine-tuning: a second training pass on minority examples.
- Out-of-distribution evaluation: testing models on data that breaks training-set patterns.
Read the paper: Increasing Robustness to Spurious Correlations using Forgettable Examples (EACL 2021).
Related founder research: adapting a model to a new task from a few examples (ICML 2018) and generating music and speech one audio sample at a time (ICLR 2017).
Our founders’ peer-reviewed papers, at ICLR, ICML, AAAI, EACL, NeurIPS and in journals including IEEE Access, are listed, each with a plain-language line, on our research papers page.
Ex-Microsoft. 10+ years of experience in AI/ML, MSc from Université de Montréal (Mila). US patent holder.
AI/ML scientist with 20+ years of research & industry experience. Ex-Google DeepMind, MIT, Harvard, Mila. McGill-Mila PhD.